Share of Voice in AI Answers: How Marketing Teams Should Measure and Report It
Measure AI share of voice across ChatGPT, Gemini and Perplexity, track brand visibility, and report LLM monitoring insights to UK marketing teams now.
Share of Voice in AI Answers: How to Measure and Report AI Visibility to Marketing Teams
Meta description: Learn how UK marketing teams can measure AI share of voice across ChatGPT, Gemini and Perplexity, with a worked calculation, leadership reporting template and practical FAQs.
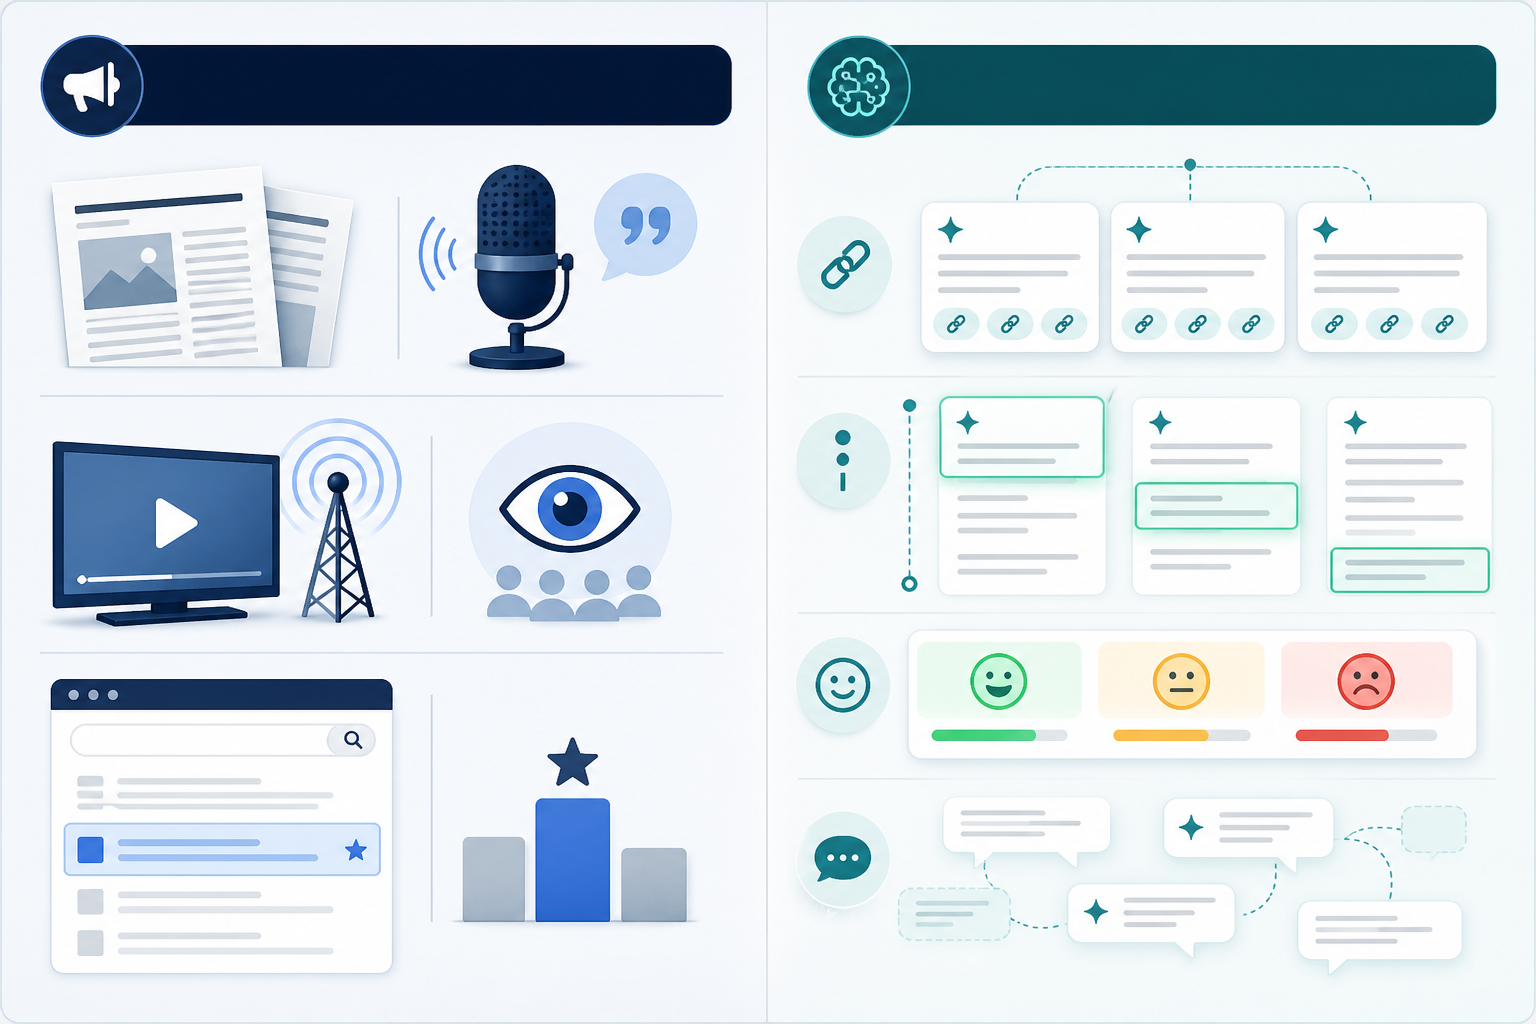
Share of voice in AI answers measures how often your brand is mentioned, cited or recommended by generative engines such as ChatGPT, Gemini and Perplexity, relative to your competitors, across the questions your buyers actually ask. Unlike traditional share of voice, which relies on impression counts, ad spend or media mentions, AI share of voice depends on query coverage, citation position and sentiment across a rotating set of AI-generated answers that can change from one week to the next.
One limitation up front, because it shapes everything that follows: this is a directional AI visibility metric. It tells you whether you are showing up in the conversation, not whether that visibility is converting into traffic, pipeline or revenue. I treat it as a leading indicator tracked alongside those numbers, never as a replacement for them, and I will return to that distinction throughout.
Below, I will explain how AI share of voice is calculated, including where my methodology is a working framework rather than an industry standard. I will also cover why it deserves a place in a marketing dashboard, how LLM monitoring supports it and how to report the results to leadership using a template you can copy.
What Is Share of Voice in the Context of AI Search?
Traditional share of voice was built for a world of static channels. You would count ad spend against category totals, tally media mentions across trade press or track average search ranking positions across a fixed keyword list. All of these approaches share a common assumption: visibility is a snapshot you can capture once and trust for weeks or months at a time.
AI search breaks that assumption. The clearest academic anchor for this is the 2024 "GEO: Generative Engine Optimization" paper — a study from Princeton, Georgia Tech, the Allen Institute for AI and IIT Delhi, presented at KDD 2024 — which examined how content sources are selected and cited within generative answers. I want to be precise about what that paper does and does not establish: it proposes methods for making content more visible to generative engines, but it does not provide the industry with a single, universally agreed AI share-of-voice standard. No such standard exists yet.
That is why I label the framework below as a working methodology rather than settled convention. Any team building an AI visibility measurement programme should keep that distinction in mind.
How AI Share of Voice Differs from Traditional Share of Voice
What is established versus what is still experimental, as I read the evidence: it is established that generative answers can compress awareness, consideration and comparison into a single block of text, and that citation behaviour differs meaningfully between engines. It is still experimental — meaning it is my working practice, not a peer-reviewed standard — how any given event should be weighted commercially and whether sentiment should be treated as a modifier or a separate metric.
A single generated response can recommend a product, compare it against two competitors and implicitly rank all three in one paragraph. This collapses what used to be three separate funnel stages into one block of text that either includes you prominently or does not include you at all.
Before going further, here is the taxonomy of events I use, because “mention” is used loosely in this space and that creates real reporting problems:
- Direct mention — your brand name appears in the generated prose (“Brand A offers…”). This counts towards the primary score.
- Citation — your domain or content is listed as a source, whether or not your brand name appears in the visible answer text. This counts towards the primary score.
- Recommendation — the engine explicitly names you as the answer to a “what should I buy/use?” prompt. This is the highest-weighted event and counts towards the primary score.
- Soft or inferred mention — the answer describes a product or feature that clearly points to your brand without naming it. I treat these as methodologically weaker because attribution is subjective unless you apply a strict entity-resolution rule, such as matching a genuinely unique product name, slogan or feature combination. I report soft mentions as a separate, confidence-weighted secondary metric rather than folding them into the headline AI SOV number.
Why AI Visibility Should Be Measured by Engine
This compression, and the taxonomy above, are why AI SOV needs to be measured per engine rather than as one universal figure. ChatGPT, Claude, Gemini, Copilot and Perplexity each draw on different training data and retrieval sources, and each shows distinct citation habits. A brand that dominates Perplexity’s citation-heavy answers might be nearly invisible in a Copilot response that draws from a narrower set of indexed sources.
I capture the exact prompt, date, market, language, model, answer text, cited sources, brand mentions, competitors, sentiment and answer position for every tracked query. I will be upfront that this is the schema we use at MentionOwl, where I work. It is one workable practice, not a rule imposed by any search provider, and you should adapt it to your needs.
Blending engines into a single number without disclosing the underlying spread hides precisely the kind of platform-specific weakness a marketing team needs to act on. A blended average can still earn a place in a top-line executive view, but it should never be presented as though the differences between platforms have disappeared.
AI Search and the UK Market
There is a UK dimension worth separating clearly from the global picture, because the two are often conflated. Google’s AI Overviews expanded from an initial US rollout into additional English-speaking markets, including the UK, during 2024. Google’s own product updates state that the feature had reached more than 200 countries and over 40 languages by mid-2025.
Separately, Pew Research Center’s 2025 analysis of US Google search behaviour found that when an AI-generated summary appeared on a results page, users clicked through to a traditional organic result in roughly 8% of visits, compared with roughly 15% when no summary appeared. Users clicked a link inside the summary itself in only about 1% of cases.
I am citing that as US evidence of a behavioural pattern worth watching, not as proof of UK click-through rates. No equivalent UK-specific study is cited here, so I would treat the two markets as directionally related rather than identical until UK-specific data exists. What the research supports, cautiously, is that UK marketing teams comparing SaaS tools, insurance products or similar considered purchases should expect a growing share of research to happen inside the answer itself rather than in the ten blue links beneath it.
How Is Share of Voice Calculated Across AI Engines?
Before the formula, three definitions underpin the rest of this section. Skipping them is where much AI SOV reporting goes wrong:
- Unit of analysis: one tracked prompt, run once per engine per cadence cycle, produces one answer. That answer can contain multiple brand events, such as a direct mention and a citation for the same brand. I count each event type separately in the raw data, then apply a deduplication rule so a single answer contributes at most one weighted score per brand: the highest-weighted event that brand achieved in that answer, not a sum of all events. Without this rule, brands mentioned repeatedly in one answer would be over-counted relative to brands that appear once, cleanly.
- Denominator: the sum of weighted events across every brand explicitly chosen for that client, typically the client plus two to four named competitors, not every brand that could theoretically appear. A wider competitor set produces a lower percentage for everyone, so I never compare AI SOV percentages across two reports that used different competitor sets.
- Query weighting: every prompt in the set counts equally by default. This is a simplification, because some prompts plausibly matter more commercially than others. I flag it as such rather than pretending the model accounts for prompt-level commercial value.
A Six-Step AI SOV Measurement Framework
Here is the six-step process I use to keep mentions, citations and sentiment separate rather than blurring them into one soft number.
- Build a representative question set. I crawl a client’s site and their category’s public forums to generate everyday purchase-decision questions a prospect would realistically type. These include comparison questions (“X vs Y for small teams”), pricing questions (“is X worth the cost”), “best tool for” questions and objection-handling questions. Most clients land on 80–150 prompts, refreshed quarterly as category language shifts.
- Run the prompt set on a cadence matched to category volatility. Weekly is my default for most categories. Daily makes sense for fast-moving categories with frequent product launches, active PR cycles or engines known to refresh answers quickly. I capture the raw answer text, cited sources, date, market, language and model version for every response. A one-off snapshot tells you far less than a tracked series because answers to the same prompt can change over time.
- Classify every brand event using the taxonomy above. Then apply the deduplication rule so one answer contributes one weighted score per brand.
- Apply position and prominence weighting. A brand named as the sole recommendation in the opening sentence carries more commercial weight than one buried in a five-way comparison table lower in the answer. My working weighting scale — illustrative, not independently validated — is 1.0 for a first-position recommendation, 0.6 for a secondary or comparative mention and 0.3 for a soft or inferred mention, reported separately. If you would rather not adopt a weighting scheme, the honest alternative is an unweighted coverage metric: the percentage of tracked prompts in which your brand appears in any of the three primary categories. That number is easier to defend and is worth reporting alongside the weighted score, not instead of it.
- Score sentiment as an independent metric. Positive, neutral and negative sentiment gets tagged using a classifier calibrated against a human-reviewed sample of at least 100 answers. Sentiment is reported alongside SOV, never multiplied into it. A brand can be mentioned frequently but unfavourably, and collapsing that into one number hides the distinction a leadership audience needs to see.
- Aggregate into per-engine and blended scores. Weighted brand events are summed per engine to produce an engine-specific SOV. A blended average is calculated across engines for the top-line view and labelled clearly as an average, not a single ground truth.
AI Share of Voice Formula
The formula, stated plainly:
AI SOV (%) = (Σ highest-weighted brand event per answer, summed across tracked prompts) ÷ (Σ same, summed across all tracked brands) × 100
Worked AI SOV Calculation Example
Here is a worked, illustrative example. The numbers demonstrate the mechanics rather than coming from a live client report. It covers a UK SaaS brand tracked across 100 prompts on three engines against two named competitors:
| Brand | First-position recommendations (×1.0) | Secondary/comparative mentions (×0.6) | Citations counted separately (informational) | Weighted core score | Soft mentions (reported separately) | Query coverage (any primary event) |
|---|---|---|---|---|---|---|
| Brand A (ours) | 18 | 15 | 34 | 27.0 | 9 | 33% |
| Competitor B | 30 | 21 | 41 | 42.6 | 6 | 51% |
| Competitor C | 12 | 21 | 22 | 24.6 | 4 | 33% |
| Total | 94.2 |
Brand A’s weighted AI SOV = 27.0 ÷ 94.2 × 100 = 28.7%, against Competitor B’s 45.2% and Competitor C’s 26.1%.
The query coverage column tells a slightly different story worth reporting alongside it: Brand A and Competitor C appear in the same share of answers overall, at 33%, but Competitor B pulls ahead specifically through first-position recommendations rather than broader coverage. That is a more precise diagnosis than a single blended figure. It says the gap is concentrated in prominence, not presence, which points to a different fix: stronger comparison content, rather than more content generally.
Why AI Share of Voice Belongs in Your Marketing Dashboard
| Reason | What it lets you decide | Limitation | Action it supports |
|---|---|---|---|
| Buyer research is shifting into the answer itself | Whether your existing organic-rank dashboard still reflects where research happens | US click-through data from Pew is not confirmed as UK-equivalent | Add AI SOV as a parallel line, not a replacement, for organic rank |
| Competitive movement in AI answers can be fast and invisible | Whether a competitor’s citation gain is new or long-standing | Requires a tracked series; a single snapshot cannot show movement | Set a weekly, or daily for volatile categories, tracking cadence |
| SOV drops often trace to one specific content asset | Whether a competitor’s rise in first-position recommendations links to a comparison page, pricing breakdown or review roundup | Correlation between a cited asset and rising SOV is not the same as proven causation | Audit the cited asset directly and brief content teams on the specific gap |
| Query coverage and prominence can move independently | Whether you have a visibility problem or a positioning problem | Neither metric alone tells you which; report both | Prioritise content that competes for first-position recommendations, not just presence |
📊 Pro tip: Resist reporting a single blended number without its components. A leadership team shown “28.7% SOV” with no breakdown will ask one question — “is that good?” — and you will not have an answer unless you can show engine-level detail, query coverage and the trend line behind it.
How to Report AI Share of Voice to Leadership
Executives do not need the six-step methodology. They need a narrative they can act on in under two minutes, backed by a table they can question. Here is the template I use, designed to be copied directly into a slide or one-pager.
Executive AI Visibility Reporting Template
Slide narrative — five fixed elements:
- Current position — “We hold 28.7% weighted AI share of voice, ranked second of three tracked competitors, with 33% query coverage.”
- Movement over the last four to eight weeks — “Up 3.2 points since our comparison-page refresh in early [month].”
- Leading competitor and their position — “Competitor B leads at 45.2% (51% query coverage), driven mainly by first-position recommendations on Perplexity.”
- Key cause, stated plainly — “Their new head-to-head comparison page is cited in 22 of our 100 tracked prompts.”
- Recommended action — “Publish a structured, data-backed comparison page targeting the same prompt cluster within four weeks.”
Supporting table for the appendix or backup slide:
| Metric | This period | Prior period | Change | Notes |
|---|---|---|---|---|
| Weighted AI SOV | 28.7% | 25.5% | +3.2 pts | Blended across three engines |
| Query coverage | 33% | 30% | +3 pts | Percentage of prompts with any primary event |
| First-position recommendation rate | 18% | 14% | +4 pts | Strongest driver of the gap versus the leader |
| Sentiment — positive share | 71% | 68% | +3 pts | Reported separately, never multiplied into SOV |
| Sample size / cadence | 100 prompts, weekly | — | — | UK market, English UK, three engines, model versions logged |
Include Verbatim AI Answer Examples
One anonymised example, because a number alone rarely convinces a room: in response to the prompt “best [category] tool for a 20-person UK team”, one tracked answer opened with “For a growing UK team, [Competitor B] is typically the strongest fit, offering…” before naming our brand two sentences later as a secondary option “worth considering for teams prioritising [specific feature].”
That is a first-position recommendation for the competitor and a secondary mention (×0.6) for us in the same answer. It is exactly the kind of granular evidence that a blended percentage alone cannot convey, and why I keep verbatim examples in the appendix of every leadership report.
What I explicitly avoid on the main slide is any claim that AI SOV predicts future market share or revenue. It does not, at least not on evidence I would be comfortable defending under questioning. It is a visibility metric that correlates with top-of-funnel attention. Treat it with the same caution you would apply to impression share in paid media: useful for diagnosing where attention is going, but not sufficient on its own to justify budget reallocation without corroborating pipeline data.
Improving AI Share of Voice Over Time
Improving AI SOV is not a single technical fix. I would be cautious of anyone suggesting your site simply is not being “read” by AI crawlers and that patching one setting will solve it. In practice, several factors interact, and it is worth being honest about which are well understood and which remain emerging practice.
Established AI Visibility and Brand Monitoring Actions
- Crawlability — confirm that AI crawlers your target engines use, including GPTBot, PerplexityBot and others, are not blocked in robots.txt. Note that Google-Extended controls whether your content can be used for Gemini and AI Overviews training and grounding specifically. It is not a universal stand-in for AI crawler access, and blocking or allowing it has no bearing on other engines’ crawlers.
- Structured data — schema markup, including Product, FAQ, Review and Organization schema, gives engines clearer signals about entities and claims. This appears to correlate with more accurate citation in practice, although I would not call it a guarantee and have not seen controlled evidence isolating its effect from other factors.
- Content usefulness — direct, well-structured answers to the exact questions in your prompt set, with clear headers, comparison tables and specific numbers, are easier for retrieval systems to extract and cite accurately.
Emerging LLM Monitoring and Optimisation Practices
- Indexation — content existing on your site does not guarantee it has been retrieved or indexed by a given engine’s underlying search layer. This varies by engine and changes over time, and there is no single reliable way to check it across all engines.
- llms.txt — some tools and a subset of engines reference an llms.txt file where a site chooses to publish one, but it is not a broadly adopted or officially required standard in the way robots.txt is. Treat it as a low-cost, unproven experiment rather than a dependable lever.
- Third-party authority — citations from independent review sites, trade press and comparison platforms appear to carry weight in several engines’ retrieval. This is consistent with why digital PR and genuine third-party coverage remain relevant. I have not seen this quantified consistently across engines, so I would describe it as a strong pattern rather than a proven rule.
- Retrieval eligibility — some engines appear to favour recently updated or freshly crawled content over static pages. This argues for a refresh cadence rather than a one-off publish-and-forget approach, although the exact recency window differs by engine and is not publicly documented in detail.
The realistic expectation is gradual, engine-by-engine improvement measured over a quarter, not a single dramatic jump after one content push.
Frequently Asked Questions About AI Share of Voice
How Is Share of Voice Different in AI Search Versus Traditional Media Monitoring?
Traditional share of voice counts fixed, countable events — ad impressions, media mentions or search rank on a static results page — captured at a point in time. AI share of voice tracks a rotating set of generated answers that change over time, measures citation position and sentiment rather than just presence, and compresses what used to be separate funnel stages into a single block of text. It requires ongoing, per-engine tracking with a defined competitor set and denominator, rather than a periodic audit.
What Counts as a Mention in an AI Answer?
I separate this into four categories: a direct mention, where your brand is named in the answer text; a citation, where your domain is listed as a source; a recommendation, where you are explicitly named as the answer to a buying question; and a soft or inferred mention, where your brand is implied but not named. Only the first three feed a primary AI SOV score. Soft mentions carry attribution risk and belong in a separate, clearly labelled metric.
How Do I Present AI Visibility Metrics to Executives?
Use a fixed five-part narrative: current position, recent movement, the leading competitor and why they are leading, the specific cause and a recommended action. Support it with a table showing coverage, sentiment, sample size and cadence. Avoid presenting a single blended number without an engine-level breakdown, and be explicit that this is a visibility metric rather than a revenue forecast.
Can Share of Voice Predict Future Market Share?
Not on the evidence available to me. AI SOV correlates with top-of-funnel visibility and can flag competitive shifts early, but I have not seen it validated — by controlled study or consistent before-and-after examples — as a predictor of market share or revenue outcomes. Treat any claim otherwise with scepticism, and track AI SOV alongside traffic, pipeline and conversion data rather than in place of them.
The Takeaway: Make AI Share of Voice Actionable
AI share of voice deserves a permanent line in your reporting, but only if it is built on a transparent methodology: a defined unit of analysis and denominator, mentions separated from citations and soft inferences, weighting labelled as illustrative rather than validated, sentiment kept as its own metric and per-engine detail reported alongside any blended average.
If you are starting from nothing, use this first-month checklist:
- Define your competitor set — two to four named competitors, fixed for at least a quarter so percentages stay comparable over time.
- Build your prompt set — 80–150 real buyer questions drawn from your site and category forums, in the market and language variant, such as English UK, that your buyers actually use.
- Choose engines and cadence — start with two or three engines your buyers are most likely to use, weekly by default and daily only if the category is genuinely volatile.
- Establish a baseline — run the full prompt set once, classify every event and calculate both weighted SOV and unweighted query coverage before changing anything.
- Report with context, not just a number — include coverage, sentiment, sample size and one verbatim example every time.
Do that, and you will have a share-of-voice metric that leadership can act on rather than dismiss.
Target keywords: share of voice, AI visibility, LLM monitoring, brand monitoring